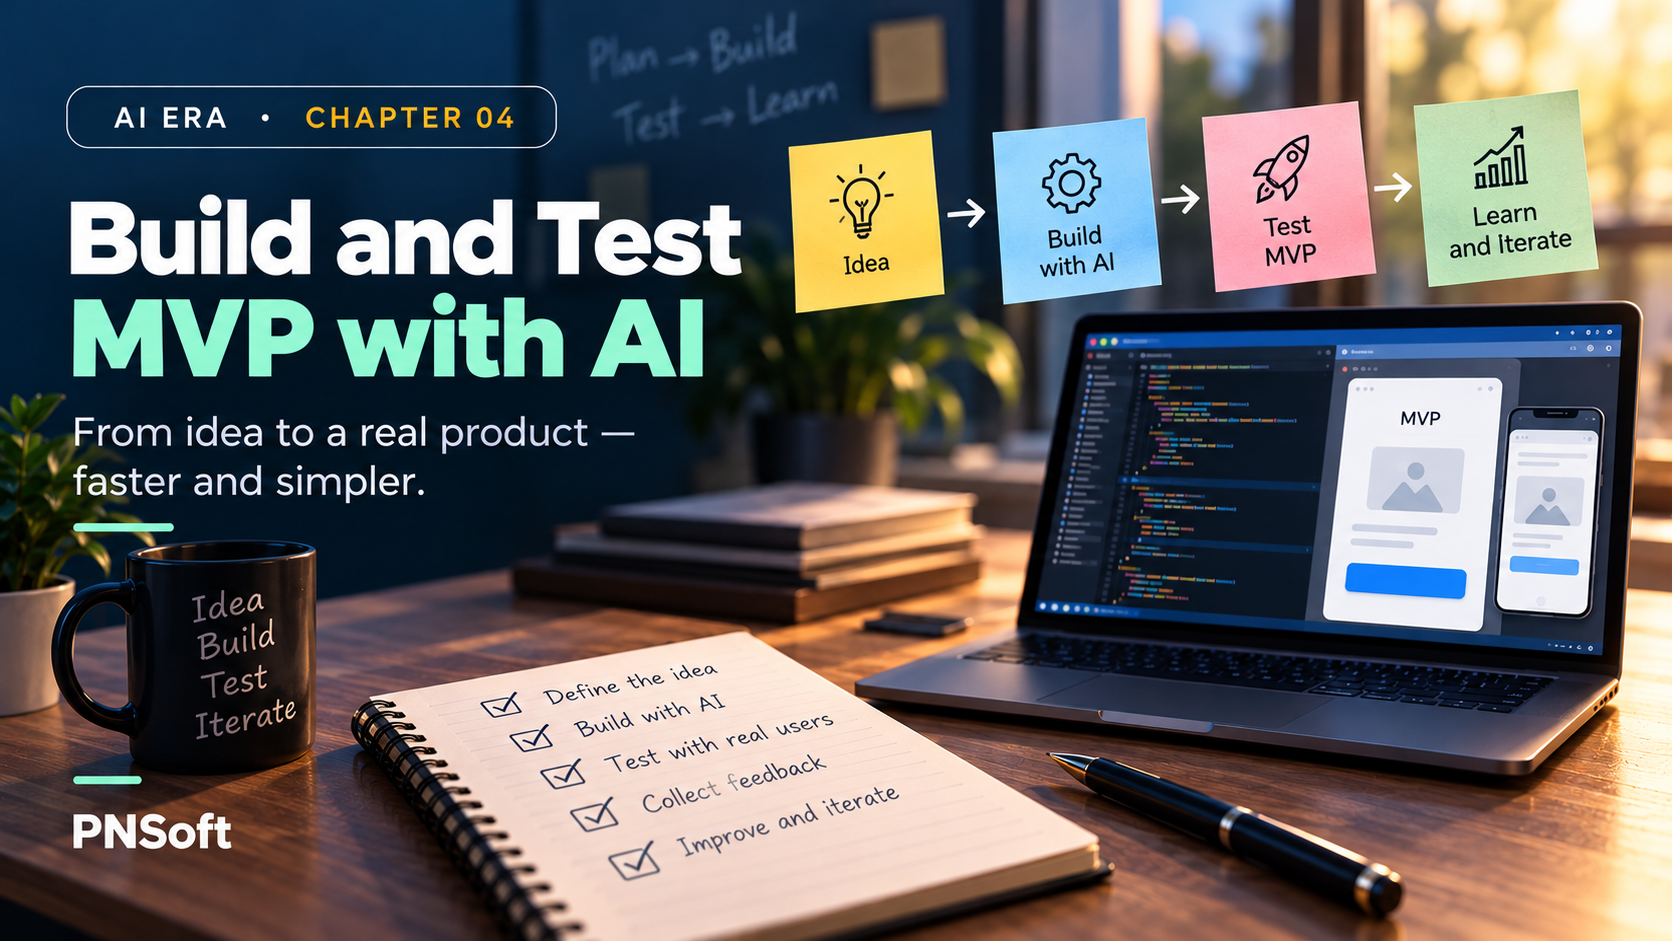
An MVP is often described by the features it leaves out. That framing can conceal the more important question: what must remain dependable for the experiment to produce useful evidence? If a request tracker loses records, exposes another organization's information, or gives misleading confirmation, users cannot fairly assess whether the workflow helps them.
The previous chapters defined a working slice and its architectural invariants. This chapter turns them into an implementation and testing plan. AI can write code and help explore failure cases, but the team must choose the consequences worth testing and decide whether the resulting evidence supports a release.
Make the MVP's learning question explicit
For our hypothetical tracker, the learning question is whether a shared assignment queue helps coordinators and technicians keep track of maintenance work. The first release needs request creation, assignment, and a way to see current status. It may not need analytics, automated scheduling, or a native mobile application.
Write down the conditions under which the test will be meaningful. Participants need access, representative requests, and enough clarity to use the workflow. The system needs reliable persistence and appropriate permissions. If these conditions fail, low usage may reflect a broken experiment rather than a weak product idea.
Keep the learning question visible in the implementation brief. When someone suggests another feature, ask whether it enables the test, removes an unacceptable risk, or can wait. This gives the team a reasoned way to protect scope without ignoring essential work.
Convert invariants into acceptance cases
Start with the invariants from Chapter 3. A user cannot read another organization's request. Repeating a creation operation does not create a second record. A notification failure does not erase saved work. Each statement should map to a test or a clear verification procedure.
Add the main user journey: a coordinator creates a request, assigns a permitted technician, and sees it in the queue. Specify what happens when required data is missing or the server cannot complete the operation. A good acceptance case makes the expected result observable without referring to a particular function's internal implementation.
Ask the agent to identify gaps in the cases before implementing them. Review its suggestions for relevance. A small application needs meaningful coverage of important consequences, rather than a large count of tests that repeat getters and formatting helpers.
Use different checks for different risks
Focused logic tests
Use fast tests for validation, state transitions, and deterministic transformations. They help isolate a failure and make local iteration efficient. They cannot establish that authentication headers, database constraints, or deployment configuration work correctly in combination.
Integration tests
Exercise the application boundary with realistic storage behavior. For the tracker, check that an assignment rejects a technician from another organization and that a repeated operation identifier returns one saved request. Where transactions matter, test against behavior close to the actual database rather than a mock that ignores constraints.
User-path checks
Walk through the workflow in a browser or appropriate client. Verify that errors are understandable, input is preserved where appropriate, and keyboard users can complete the form. A successful server response does not prove that the interface communicates the result correctly.
Give the agent a testable implementation task
A useful instruction names the behavior and evidence: implement request creation using the established data layer, enforce organization membership on the server, preserve the form on validation errors, and include a check for a repeated submission. Ask for a summary of changed behavior and any checks that could not run.
Review tests as carefully as production code. An agent may accidentally encode its own assumption as the expected result. If both implementation and test misunderstand the requirement, a green suite can reinforce the mistake. Compare the test's setup and assertion with the original acceptance case.
Do not weaken a meaningful test merely to make a build pass. Investigate whether the failure reflects a requirement change, a defect, or a test-environment limitation. Record the reason when a test is revised so that future maintainers can understand the intended behavior.
Exercise uncertainty and failure
Test a save that returns slowly, a user who submits twice, and a request made after the user's permissions change. Consider a session expiring while the form is open. These situations often reveal assumptions about timing and authority that the happy path leaves untouched.
For integrations, distinguish a provider rejecting a request from a request whose outcome is unknown. Retrying an unknown operation may be safe for a read and unsafe for a payment or duplicate notification. Define how the application identifies a completed operation and how support staff can recover an unresolved one.
Use controlled failures in a test environment. Avoid damaging production records just to demonstrate resilience. If a scenario cannot be tested before the first release, decide whether the risk is acceptable, reduce the scope, or delay the affected capability.
Make the deployment reproducible
Keep build instructions, runtime requirements, and necessary configuration names in the repository. Store secret values through the hosting platform's supported secret mechanism. The person releasing should know which environment receives the change and which database migrations will run.
Run the appropriate build and checks against the source state that will be deployed. A successful test before a later unreviewed edit does not verify the final artifact. Retain enough provenance to identify the released commit and return to a prior version if needed.
Before migration, understand whether the change is compatible with the previous application version. A destructive schema change can make rollback harder than redeploying an old bundle. Small teams benefit from keeping early migrations conservative and separating data cleanup from unrelated feature work.
Observe the MVP after release
Choose signals that show whether the workflow completes and where it fails. Useful technical signals include failed saves, authorization rejections, and unresolved background jobs. Useful product signals include whether a request receives an owner and whether participants return to update its status.
Avoid collecting more personal information than the question requires. Logs should help diagnose behavior without becoming a second store of sensitive request content. Decide who can access them and how long they remain useful.
Give participants a clear way to report a problem. A small release can be supported through a named contact and a simple issue record. If nobody owns follow-up, early failures may be interpreted as a lack of interest when participants have simply given up trying to get help.
Review the experiment alongside the software
At the end of the pilot window, examine both reliability and usefulness. If the system worked but users did not complete the job, investigate the workflow fit. If the system failed repeatedly, improve reliability before drawing strong conclusions about demand.
Ask what manual support was required. An MVP that works only because an engineer repairs records each afternoon has revealed an operational dependency. That can be acceptable for a disclosed experiment, but it must be counted when deciding whether to continue.
Conclusion: test the promise behind the feature
An AI-assisted MVP deserves the same clarity about data, access, failure, and user outcomes as any other software. Scope can be small while accountability remains explicit. Select checks that test the promise you are making, keep deployment evidence tied to the released source, and use pilot results to guide the next decision.
Before progressing, write a release checklist with the learning question, essential acceptance cases, known limitations, and rollback owner. Chapter 5 will consider what changes when a successful MVP begins to carry recurring customer expectations.